

Platonic Representations for Poverty Mapping: Unified Vision-Language Codes or Agent-Induced Novelty?
Authors: Satiyabooshan Murugaboopathy | Connor T. Jerzak | Adel Daoud
TL;DR: What this poverty mapping study shows
We combine satellite imagery with AI-generated text to predict household wealth across more than 60,000 African neighborhoods, using the International Wealth Index (IWI) as our ground truth. Fusing images, AI search agents, and language models explains about 77% of the variation in local wealth, compared with about 63% for satellite images alone, and we release a large multimodal dataset to support future work.
- Problem: Poverty surveys are expensive, infrequent, and often miss remote or fast-changing areas.
- Approach: Combine satellite images with two types of text: LLM “neural memory” descriptions and AI-agent web search summaries.
- Key finding: Blending images with LLM text sharply boosts performance; LLM knowledge outperforms web-searched text.
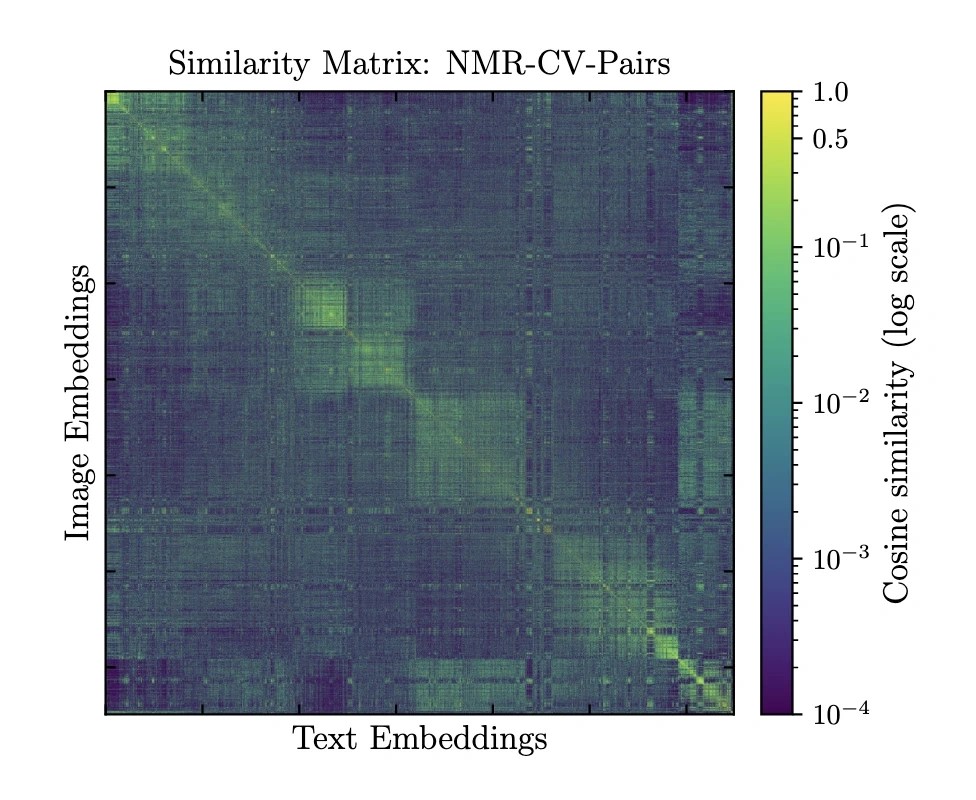
- Representation: Image and text embeddings show moderate overlap (cosine similarity ≈ 0.60), suggesting a shared latent “code” of material well‑being.
- Impact: More accurate, scalable poverty maps to help governments and NGOs target resources across Africa.
Why is poverty hard to measure in low- and middle-income countries?
Traditional poverty measurement relies on detailed household surveys such as the Demographic and Health Surveys (DHS). These surveys provide reliable data on wealth and living standards, but they are costly, infrequent, and often miss remote or rapidly changing areas.
At the same time, policymakers, NGOs, and researchers urgently need up‑to‑date, fine‑grained information on where poverty is deepening or improving. Without this, it is hard to target aid, design effective programs, or evaluate progress toward development goals.
Why satellite images alone are not enough
Satellite imagery has become a powerful proxy for economic activity. Features like road networks, building density, and land use patterns can reveal a lot about local wealth and infrastructure. However, images alone cannot capture:
- Historical shocks (e.g., conflict, droughts, policy reforms).
- Cultural and social dynamics that affect material well‑being.
- Nuanced economic context that may not be visible from above.
This creates an opportunity for multimodal AI to fill the gap by combining what satellites “see” with what text sources “say.”
How does our multimodal AI model combine satellite images and text?
Our core question is simple: Do poverty and wealth leave consistent, recoverable traces in both images and text? And if so, can AI learn a shared representation of these traces that improves poverty prediction?
To answer this, we build five prediction pipelines that mix and match satellite imagery with different kinds of AI‑generated and AI‑retrieved text.
Five complementary prediction pipelines
- 1. Vision-only (images): A computer vision model looks at cloud‑free Landsat satellite images and predicts wealth based on physical cues like infrastructure and land use.
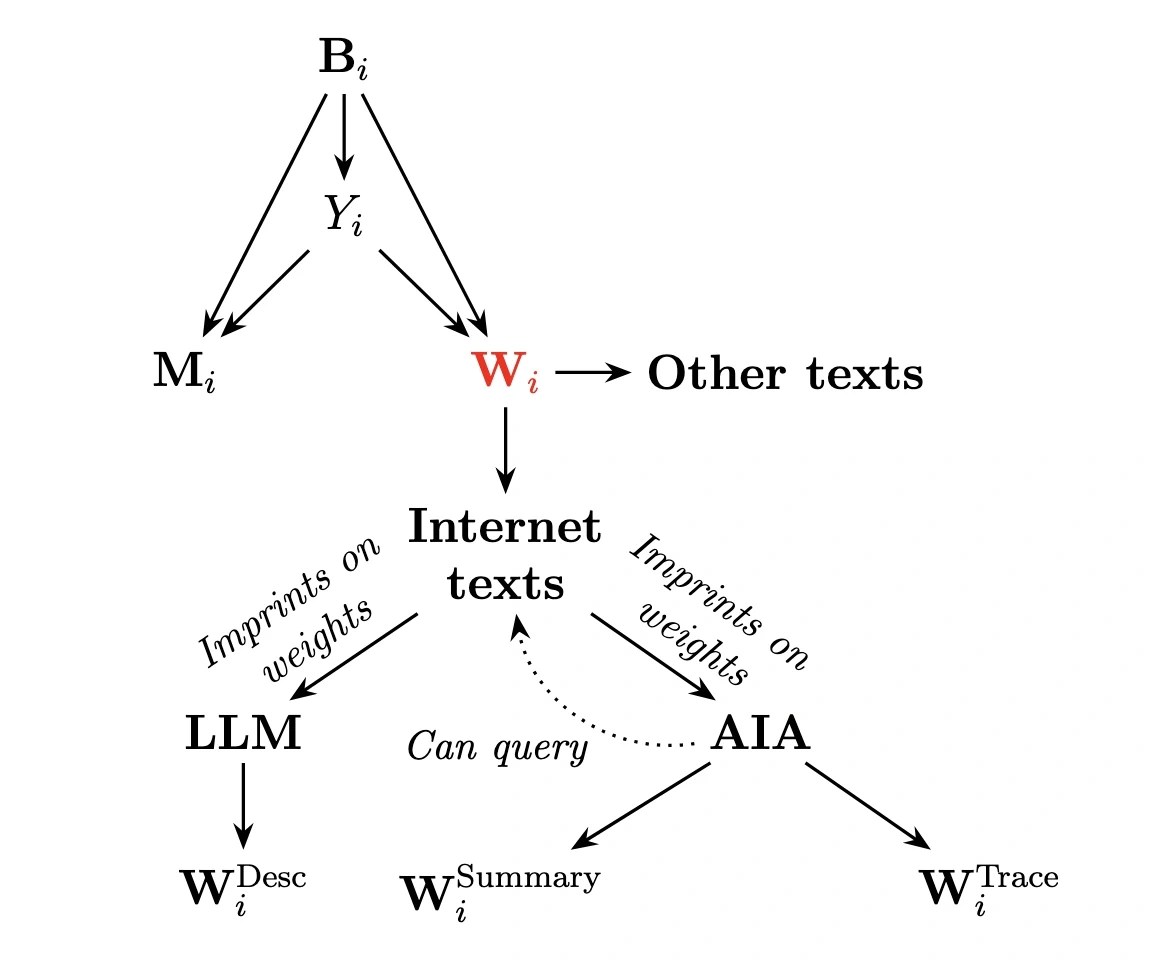
- 2. LLM-only (“neural memory” text): A large language model (LLM) gets only the location and year, and generates a description plus a wealth prediction from its internal knowledge of geography, history, and economics.
- 3. AI Search Agent (web text): An AI agent uses tools like web search and Wikipedia to retrieve real‑world text about the location, then summarizes that information and predicts wealth.
- 4. Joint image–text encoder: A multimodal encoder fuses satellite images with text embeddings into a shared latent representation, aiming to capture a unified “code” for material well‑being.
- 5. Ensemble: A final model combines all signals (vision, LLM text, agent‑retrieved text) to produce a robust wealth prediction.
Two guiding ideas we test
- Platonic Representation Hypothesis: There is a shared, underlying representation of concepts like wealth that both images and text can approximate. In other words, different modalities converge on similar “Platonic” codes.
- Agent-Induced Novelty Hypothesis: An AI agent that actively searches the web may uncover new, dynamic information not already baked into an LLM’s internal knowledge, adding complementary signals for prediction.
What data did we use across 60,000+ African neighborhoods?
Our study focuses on DHS clusters (neighborhood‑level units) across Africa between 1990 and 2020. For each cluster, we extract ground‑truth wealth, imagery, and text.
Ground-truth: International Wealth Index (IWI)
We use the International Wealth Index (IWI) as our main measure of material well‑being. IWI is a composite score between 0 and 100, built from household assets and living conditions, aggregated to the neighborhood (cluster) level.
Visual data: Satellite imagery
For every cluster, we collect high‑resolution Landsat satellite imagery:
- Cloud‑free daytime composites at roughly 30m resolution.
- Multiple spectral bands (e.g., RGB and infrared) capturing infrastructure and land cover.
- Centered on each DHS cluster’s coordinates.
Text data: LLM descriptions and AI-agent web searches
We generate two main types of text for each location:
- LLM-generated descriptions (neural memory): An LLM receives only the location name, coordinates, and year. Without any external tools, it produces a narrative about the area and a predicted wealth score.
- AI Search Agent text (web-derived): An LLM‑driven agent queries sources like Wikipedia, research portals, and open data sites, then merges these into a summary and wealth prediction. The agent’s raw traces and summaries are also embedded as text features.
The resulting corpus — images, LLM text, agent traces, and IWI labels — forms our IWI‑Africa‑Multimodal dataset, spanning approximately 60,000 clusters across the continent.
What did we actually find?
In short, combining satellite images with AI‑generated text clearly improves poverty prediction, and LLM “memory” is surprisingly strong on its own.
Fusing images and text boosts accuracy
When we blend satellite imagery with LLM‑generated descriptions, the model explains about 77% of the variation in neighborhood wealth (R² ≈ 0.77) on out‑of‑sample data. By comparison:
- Images alone: roughly 63% of variation explained (R² ≈ 0.63).
- Best text-only model (LLM neural memory): around 67% of variation explained (R² ≈ 0.67).
The multimodal model also holds up under tougher tests, such as predicting in countries or years not seen during training, indicating better generalization.
LLM knowledge outperforms web search text
We originally expected that an AI Search Agent, which actively crawls the web, would add a lot of extra value. Instead, we find:
- LLM-only text (no external tools) typically predicts wealth more accurately than web‑retrieved text.
- Agent‑retrieved text does add some complementary information in certain cases, but the gain is modest and inconsistent.
This gives stronger support for the Platonic Representation Hypothesis than for strong agent‑induced novelty in this setting: the LLM’s internal representation already encodes much of the socio‑economic structure needed for accurate prediction.
Do images and text “agree” in representation space?
To test representational convergence, we compare embeddings from images and text after alignment. We find:
- Moderate cross‑modal similarity, with median cosine similarity around 0.60 for matched locations.
- Significant positive similarity, far above what we would expect from random embeddings.
- Geographically coherent patterns: nearby regions often show similar alignment structures between image and text representations.
This suggests that satellite imagery and language models are, to a meaningful extent, learning a shared latent “code” of material well‑being, while still contributing complementary details.
Why do these results matter for policy and social impact?
More accurate and scalable poverty maps are not just an academic exercise. They can directly support targeted interventions, smarter resource allocation, and more equitable development.
Practical benefits for governments and NGOs
- Fill data gaps: Generate up‑to‑date wealth estimates in areas where surveys are rare or missing.
- Target aid: Identify neighborhoods that are consistently under‑served or left out of infrastructure investments.
- Monitor change: Track how material well‑being evolves over time, including after shocks or policy reforms.
Why LLM “neural memory” is especially promising
The LLM-only pipeline is attractive for real‑world deployments because it:
- Requires only a single LLM call per location (no complex web search stack).
- Performs nearly as well as the best multimodal system in many settings.
- Is easier to scale across countries and time periods.
In resource‑constrained environments, this makes LLM‑based poverty mapping a cost‑effective tool for development practitioners.
How can you access the IWI-Africa-Multimodal dataset?
To support open research and reproducibility, we release a large multimodal dataset that pairs:
- ~60,000 DHS clusters across Africa (1990–2020).
- Landsat satellite images centered on each cluster.
- LLM-generated descriptions conditioned on location and year.
- AI Search Agent traces and summaries.
- International Wealth Index (IWI) scores as labels.
The dataset, called IWI‑Africa‑Multimodal, is hosted on Hugging Face. To link it with the full DHS data, users must register with the DHS Program and agree to its privacy and data use policies.
What are the limitations and next steps?
Like any empirical study, our approach has limitations and should be interpreted with care, especially for causal claims.
Key limitations
- Sampling bias: DHS clusters may under‑represent the most remote or marginalized areas, which affects where we can reliably predict wealth.
- Post-treatment information: Agent‑retrieved web text could contain information that occurs after the survey year, complicating causal interpretations.
- Computational cost: Agent‑based web search at continental scale is expensive and may be hard to sustain for global applications.
Future research directions
- Integrating causal inference tools to handle text‑specific issues like post‑treatment bias more explicitly.
- Exploring fairness and bias in multimodal poverty maps across regions, ethnic groups, and urban–rural divides.
- Further testing the Platonic Representation and Agent‑Induced Novelty hypotheses in other domains beyond poverty mapping.
Overall, our results suggest that AI can meaningfully augment, but not replace, traditional survey‑based approaches. Used responsibly, multimodal AI can help close data gaps and support more equitable development policy.
Frequently Asked Questions
What is the International Wealth Index (IWI)?
The International Wealth Index (IWI) is a 0–100 score that summarizes household assets and living conditions (such as housing quality and access to basic services). In this study, we aggregate IWI at the neighborhood (DHS cluster) level to measure local material well‑being.
Does this model replace household surveys?
No. Our approach is designed to complement, not replace, traditional surveys. It can help interpolate between survey waves, fill spatial gaps, and guide where new surveys or ground work would be most useful.
Why does the LLM-only model perform so well?
Large language models encode rich background knowledge about geography, history, and development patterns. Even when given only a location and year, the model can leverage this internal “neural memory” to approximate typical wealth levels, especially when trained and calibrated on many examples.
Can this approach be extended beyond Africa?
In principle, yes. The same multimodal framework can be applied to other regions, provided that comparable survey data (for ground truth), satellite imagery, and place‑specific text are available. However, performance and fairness should be evaluated carefully in each new context.
References
@article{murugaboopathy2026platonic,
  title={Platonic Representations for Poverty Mapping: Unified Vision-Language Codes or Agent-Induced Novelty?},
  author={Murugaboopathy, Satiyabooshan and Connor T. Jerzak and Adel Daoud},
  journal={Proceedings of the 7th International Conference on Social Computing (ICSC 2026), of Communications in Computer and Information Science},
  year={2026},
  volume={},
  pages={},
  publisher={Springer Nature}
}[Video]
Related Work
@article{daoud2026+planetary,
  title={Planetary Causal Inference: Understanding the Environment, Society, and Economy through Earth Observation and AI Systems},
  author={Daoud, Adel and Connor T. Jerzak},
  journal={A Book Project},
  year={2026+},
  volume={},
  pages={},
  publisher={Under contract with Cambridge University Press}
}
–
@article{pettersson2026debiasing,
  title={Debiasing Machine Learning Predictions for Causal Inference Without Additional Ground Truth Data: 'One Map, Many Trials' in Satellite-Driven Poverty Analysis},
  author={Pettersson, Markus B. and Connor T. Jerzak and Adel Daoud},
  journal={Proceedings of the AAAI Conference on Artificial Intelligence (AAAI-2026)},
  year={2026},
  volume={40},
  pages={39106-39115},
  publisher={}
}–
@article{daoud2026chinese,
  title={Chinese vs. World Bank Development Projects: Insights from Earth Observation and Computer Vision on Wealth Gains in Africa, 2002-2013},
  author={Daoud, Adel and Cindy Conlin and Connor T. Jerzak},
  journal={World Development},
  year={2026},
  volume={202},
  pages={107328},
  publisher={}
}–
@article{fucheng2025optimizing,
  title={Optimizing Multi-Scale Representations to Detect Effect Heterogeneity Using Earth Observation and Computer Vision: Applications to Two Anti-Poverty RCTs},
  author={Fucheng, Warren Zhu and Connor T. Jerzak and Adel Daoud},
  journal={Proceedings of the Fourth Conference on Causal Learning and Reasoning (CLeaR), Proceedings of Machine Learning Research (PMLR)},
  year={2025},
  volume={},
  pages={},
  publisher={}
}[Video][>]
–
@article{jerzak2023image,
  title={Image-based Treatment Effect Heterogeneity},
  author={Jerzak, Connor T. and Fredrik Johansson and Adel Daoud},
  journal={Proceedings of the Second Conference on Causal Learning and Reasoning (CLeaR), Proceedings of Machine Learning Research (PMLR)},
  year={2023},
  volume={213},
  pages={531-552},
  publisher={}
}–
@article{nicolas audinet de pieuchon 2025benchmarking,
  title={Benchmarking Debiasing Methods for LLM-based Parameter Estimates},
  author={Nicolas Audinet de Pieuchon and Adel Daoud and Connor T. Jerzak and Moa Johansson and Richard Johansson},
  journal={Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing (EMNLP)},
  year={2025},
  volume={},
  pages={},
  publisher={},
  doi={}
}–
@article{sakamoto2026scoping,
  title={A Scoping Review of Earth Observation and Machine Learning for Causal Inference: Implications for the Geography of Poverty},
  author={Sakamoto, Kazuki and Connor T. Jerzak and Adel Daoud},
  journal={Hall, Ola and Ibrahim Wahab (eds.), Geography of Poverty},
  year={2026},
  volume={},
  pages={},
  publisher={Edward Elgar Publishing (Cheltenham, UK)}
}